iFANN
    Search iFANN...
    Log in
    Home
    News
    Videos
    Photos
    GIFs
    Explore
    Polls
    Awards
    iFAMOUS
    Wiki
    Anime
    Rooms
    Notifications
    Messages
    Bookmarks
    Profile
    WikiAwardsiFAMOUSRankingsIndustriesCreator RewardsUser RewardsTermsPrivacyCommunity GuidelinesTakedown / DMCAHelpDevelopers

    © 2026 iFANN

    Home
    Search
    Messages
    Alerts
    Profile
    Photo
    Nate
    Nate@nate_51235m
    📱Qwen💭AI💭Tech
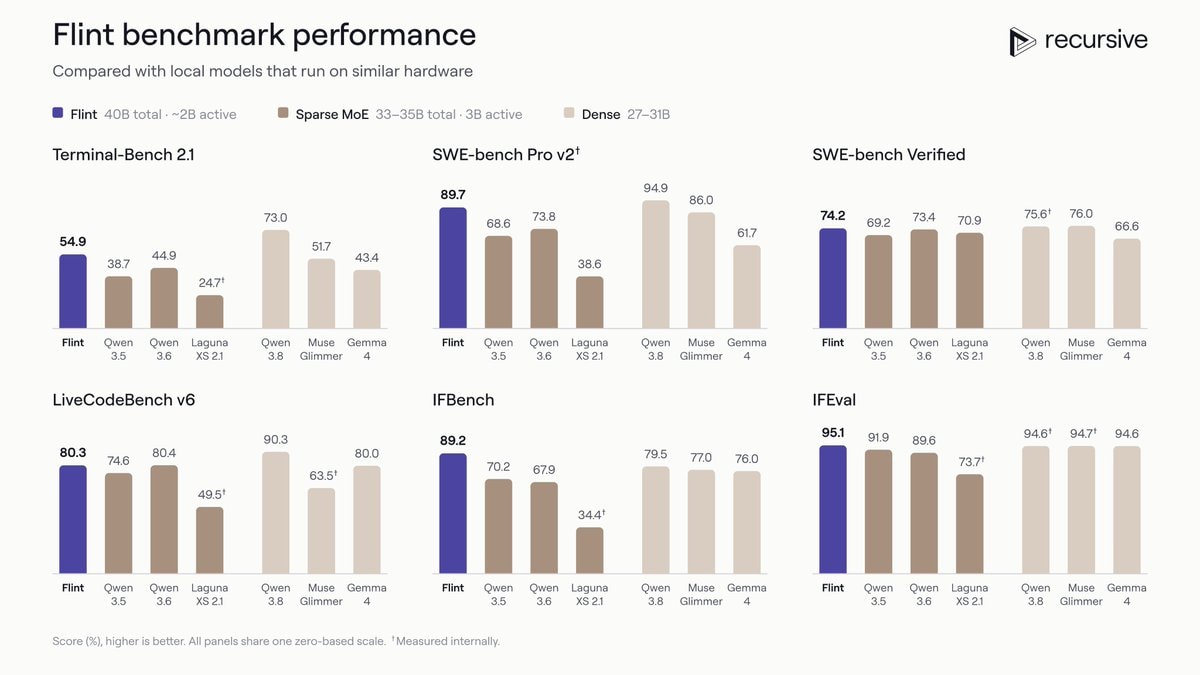
    Flint benchmark performance vs local models

    @nate_512Istg the scale of this release is barely being talked about. A US lab dropped a 40B open-weight coding model that actually tops three major benchmarks against Qwen, Muse, and Gemma. You get over 125 tokens per second on a MacBook or 150+ on RTX Spark hardware without any per-token fees or usage limits. Your personal laptop is finally the real endpoint for this tech.

    View original post
    Flint benchmark performance vs local models

    Photo by @nate_512· Oct 21, 2026· Qwen

    About this photo

    This is a data visualization of benchmark performance for different AI models. The focus is on bar charts comparing "Flint" against other models like "Qwen", "Muse", and "Gemma" across various benchmarks. The mood is informative and technical, presented in a clean, modern graphic design style. A notable detail is the use of different colored bars and labels to distinguish between model types and their performance scores. The title "Flint benchmark performance" is prominently displayed at the top, with the subtitle "Compared with local models that run on similar hardware". A logo for "recursive" is in the top right corner.

    See all Qwen photosRead the Qwen wiki

    ?

    More Qwen photos

    See all Qwen photos
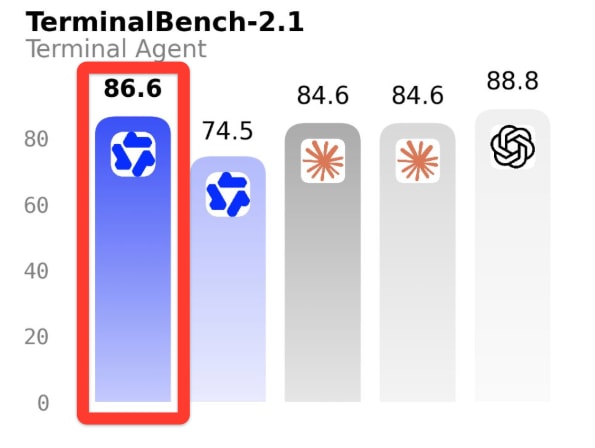
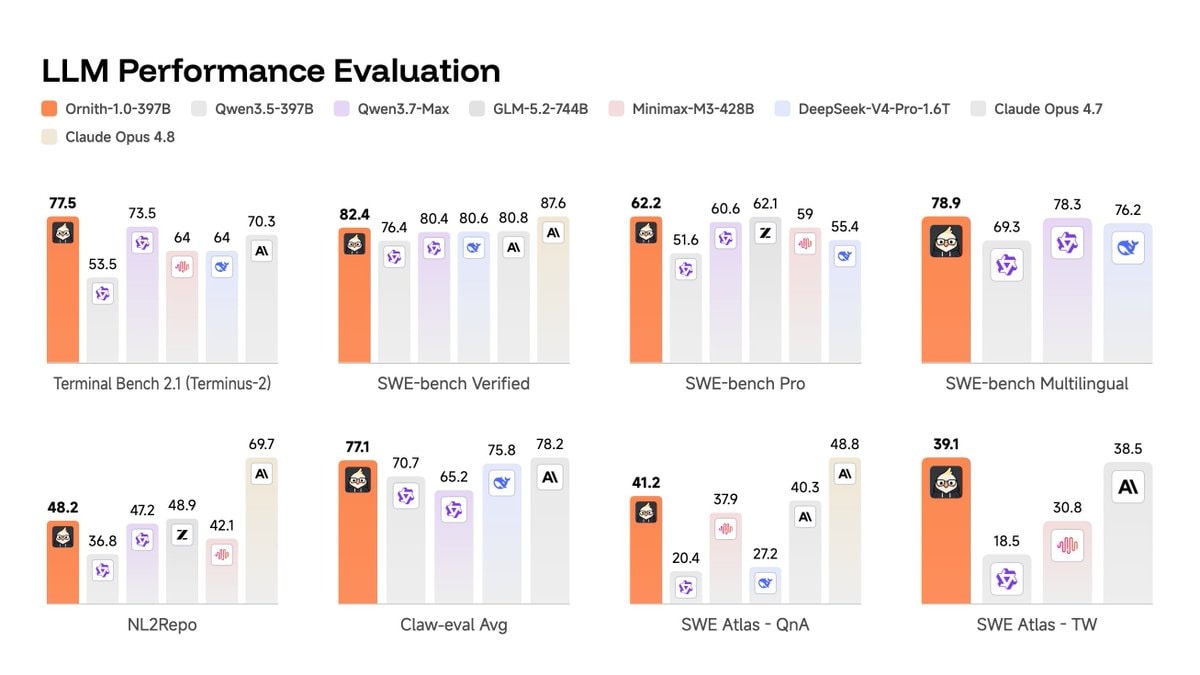
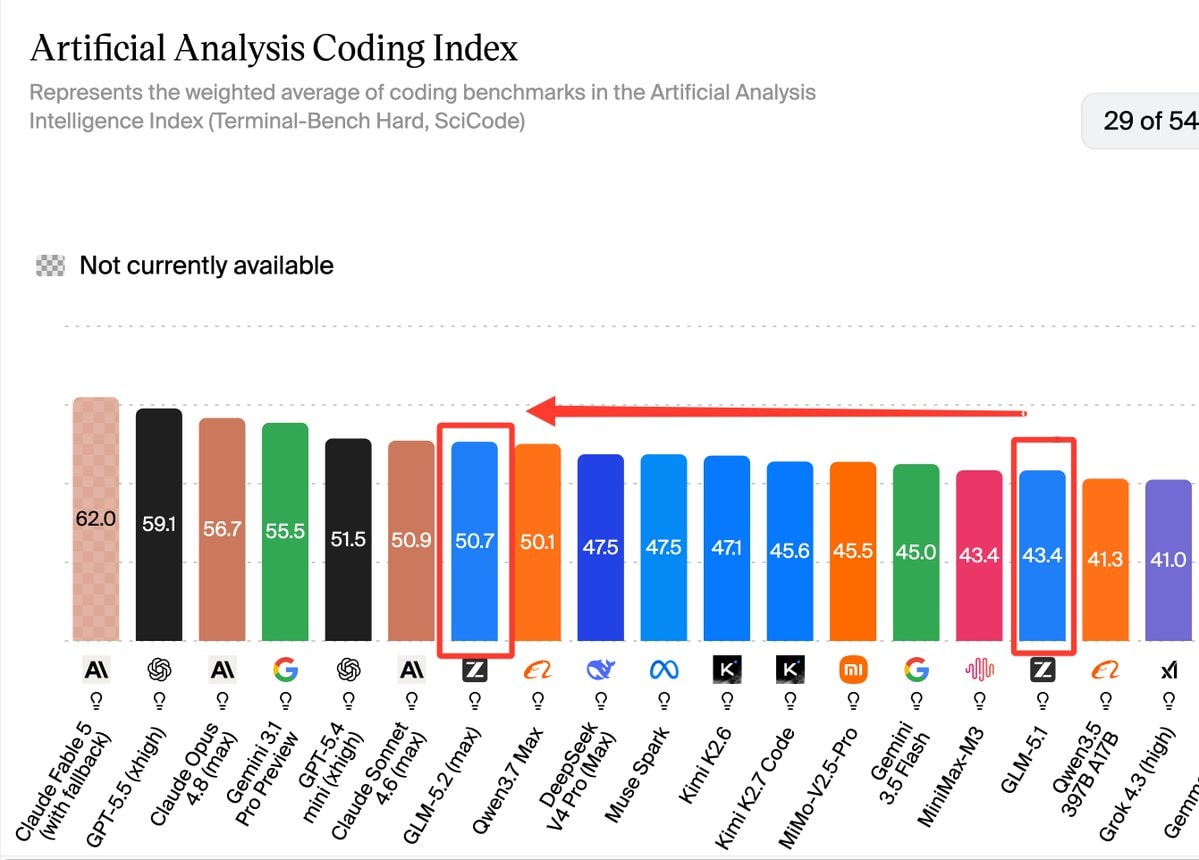
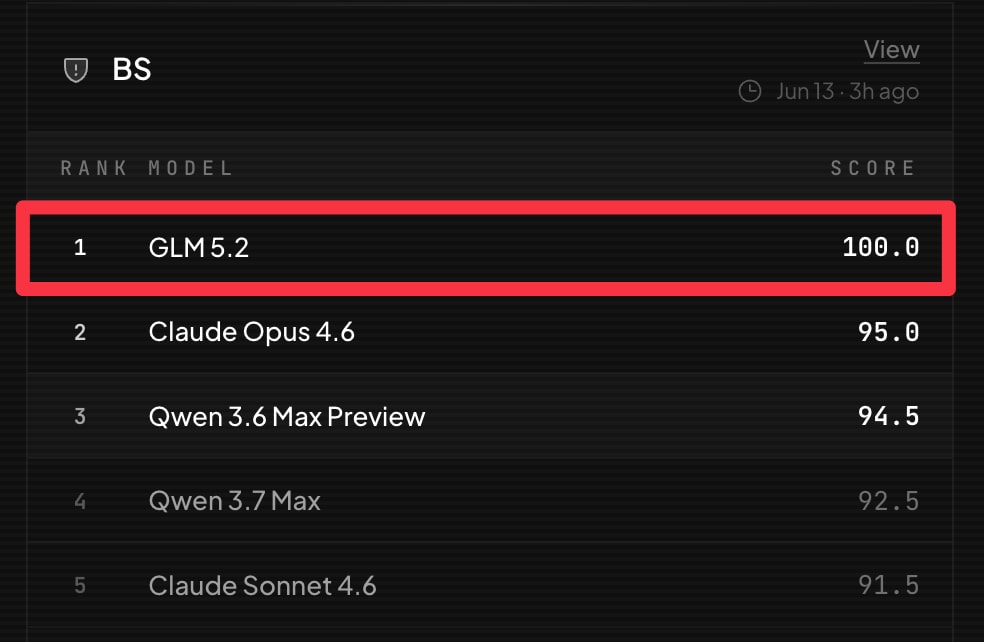
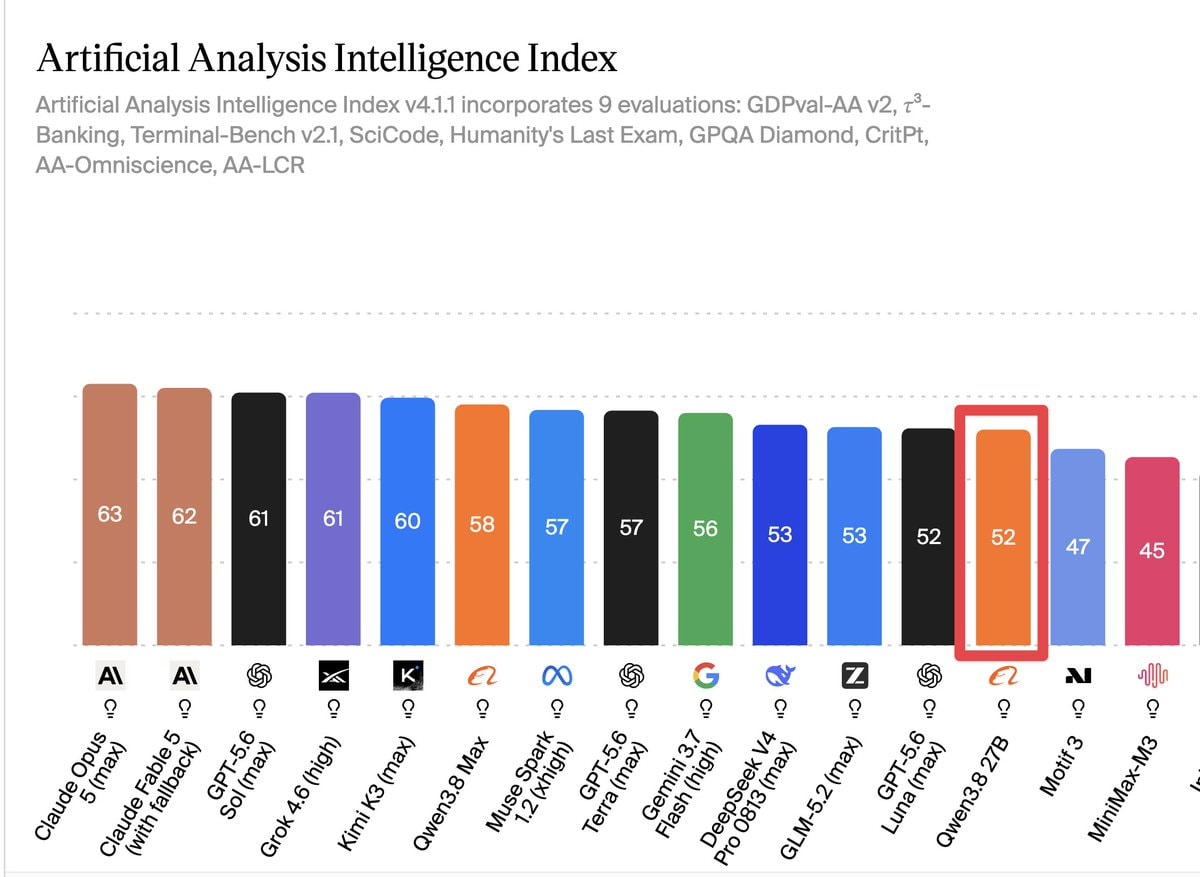
    Google WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreOrnith-1.0 agentic coding LLM performanceOrnith-1.0 agentic coding LLM performanceGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS
    Photo
    Nate
    Nate@nate_51235m
    📱Qwen💭AI💭Tech
    Flint benchmark performance vs local models

    @nate_512Istg the scale of this release is barely being talked about. A US lab dropped a 40B open-weight coding model that actually tops three major benchmarks against Qwen, Muse, and Gemma. You get over 125 tokens per second on a MacBook or 150+ on RTX Spark hardware without any per-token fees or usage limits. Your personal laptop is finally the real endpoint for this tech.

    View original post
    Flint benchmark performance vs local models

    Photo by @nate_512· Oct 21, 2026· Qwen

    About this photo

    This is a data visualization of benchmark performance for different AI models. The focus is on bar charts comparing "Flint" against other models like "Qwen", "Muse", and "Gemma" across various benchmarks. The mood is informative and technical, presented in a clean, modern graphic design style. A notable detail is the use of different colored bars and labels to distinguish between model types and their performance scores. The title "Flint benchmark performance" is prominently displayed at the top, with the subtitle "Compared with local models that run on similar hardware". A logo for "recursive" is in the top right corner.

    See all Qwen photosRead the Qwen wiki

    ?

    More Qwen photos

    See all Qwen photos
    Google WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreOrnith-1.0 agentic coding LLM performanceOrnith-1.0 agentic coding LLM performanceGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS