Back to Qwen
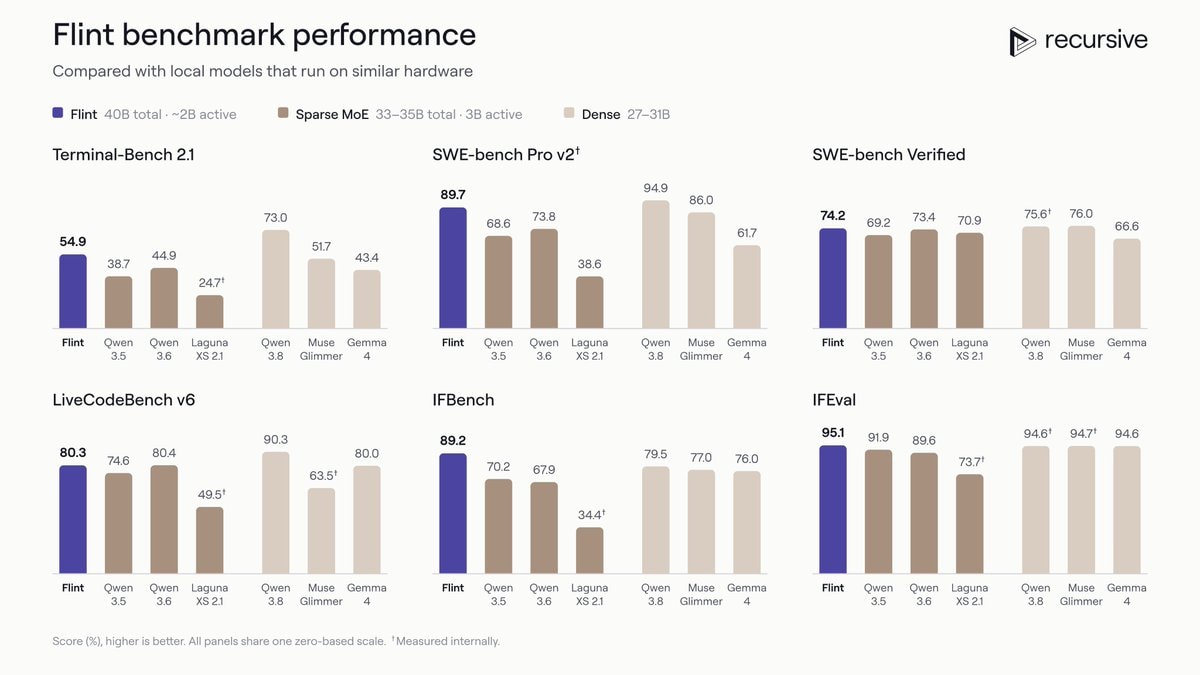
Flint benchmark performance vs local models
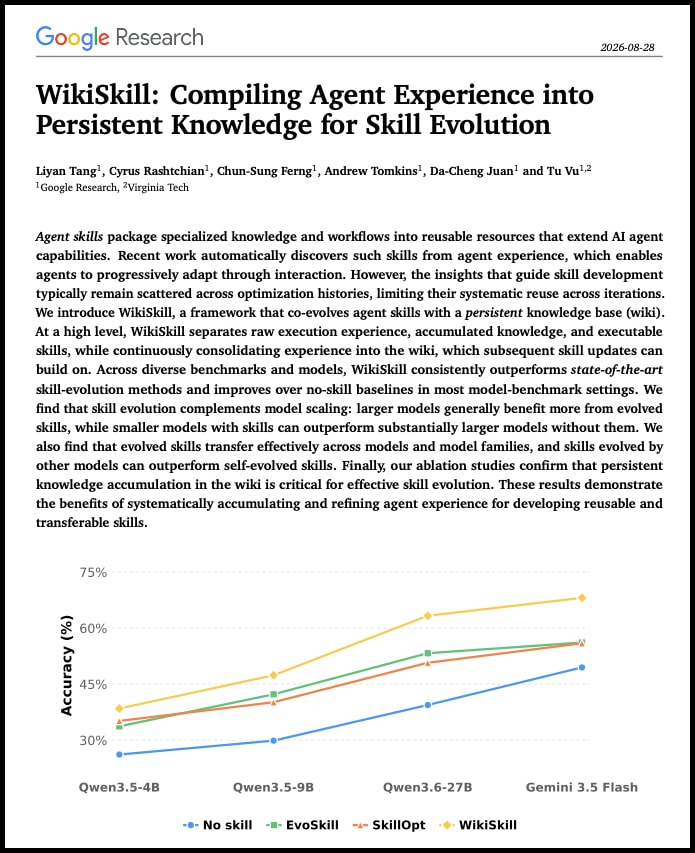
Google WikiSkill paper SKILL.md agents
AI models Kimi Qwen DeepSeek GLM MiniMax
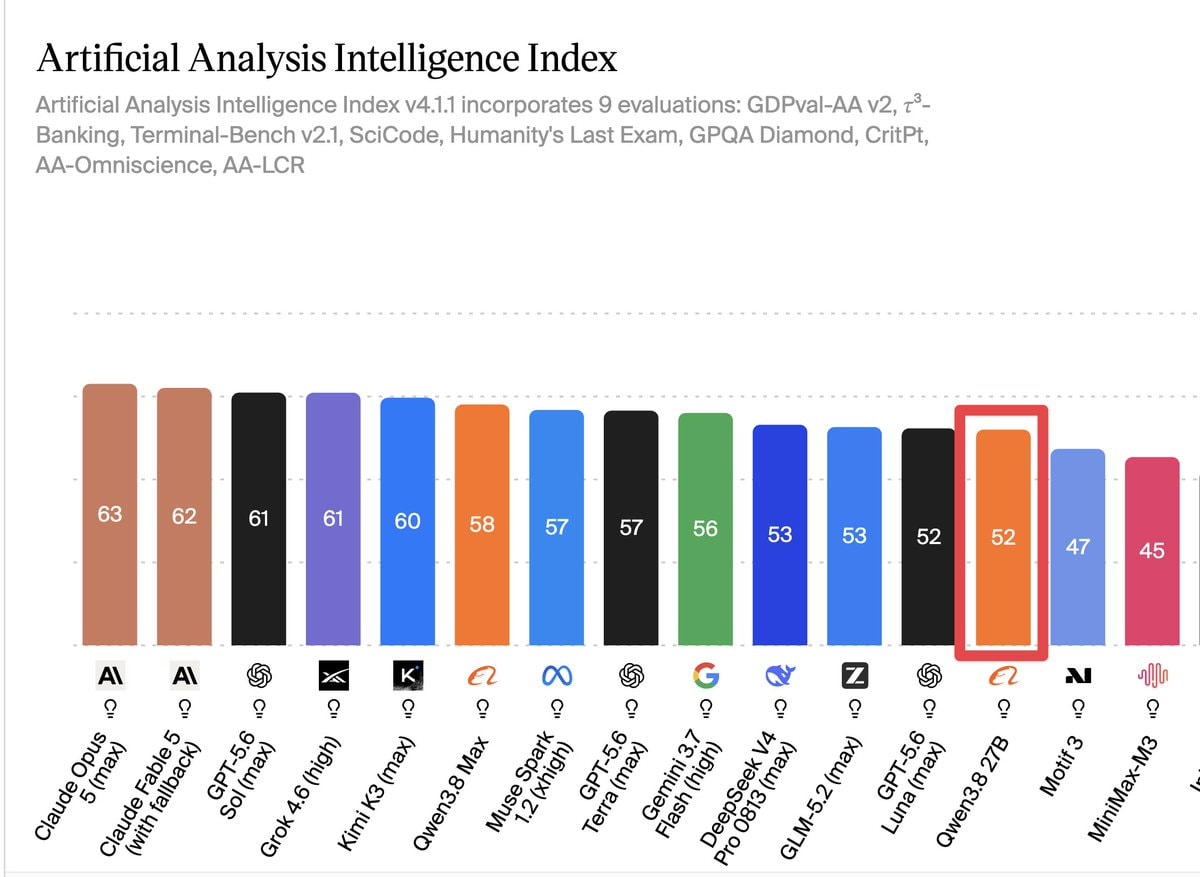
Qwen 3.8 27B ties GPT 5.6 Luna
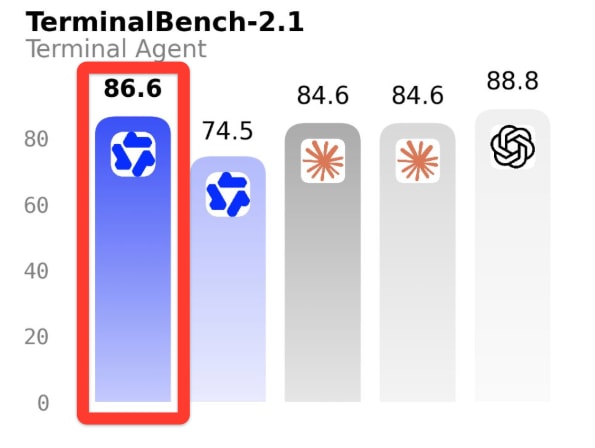
Qwen 3.8 Max TerminalBench score
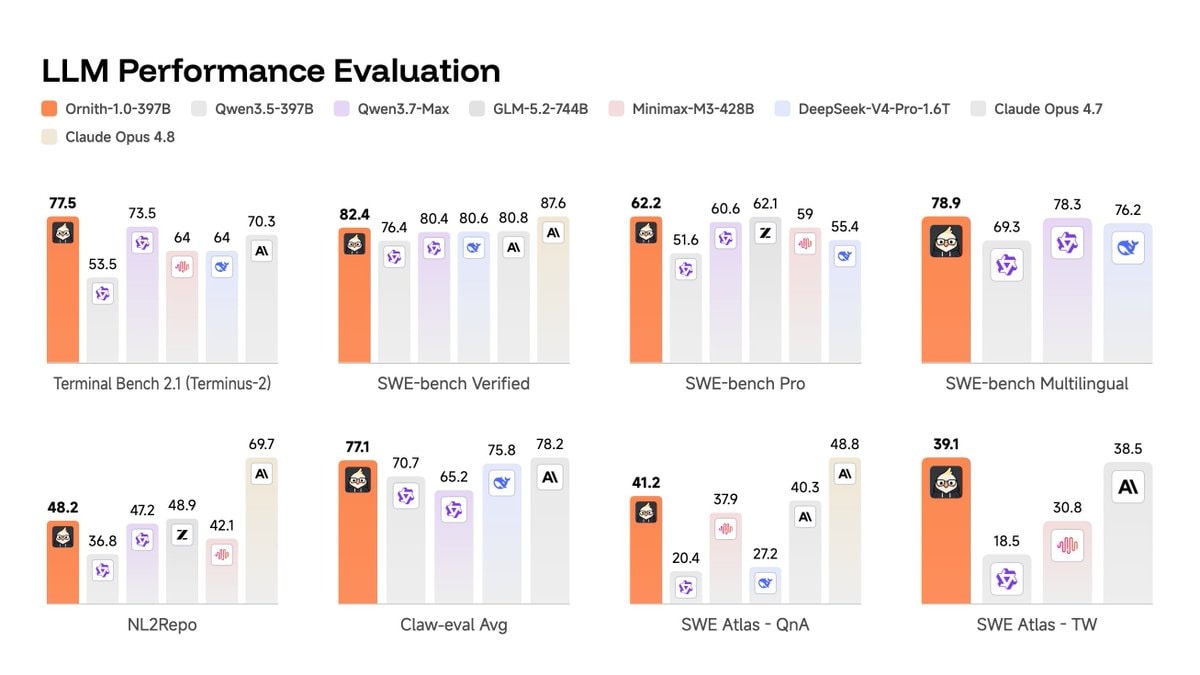
Ornith-1.0 agentic coding LLM performance
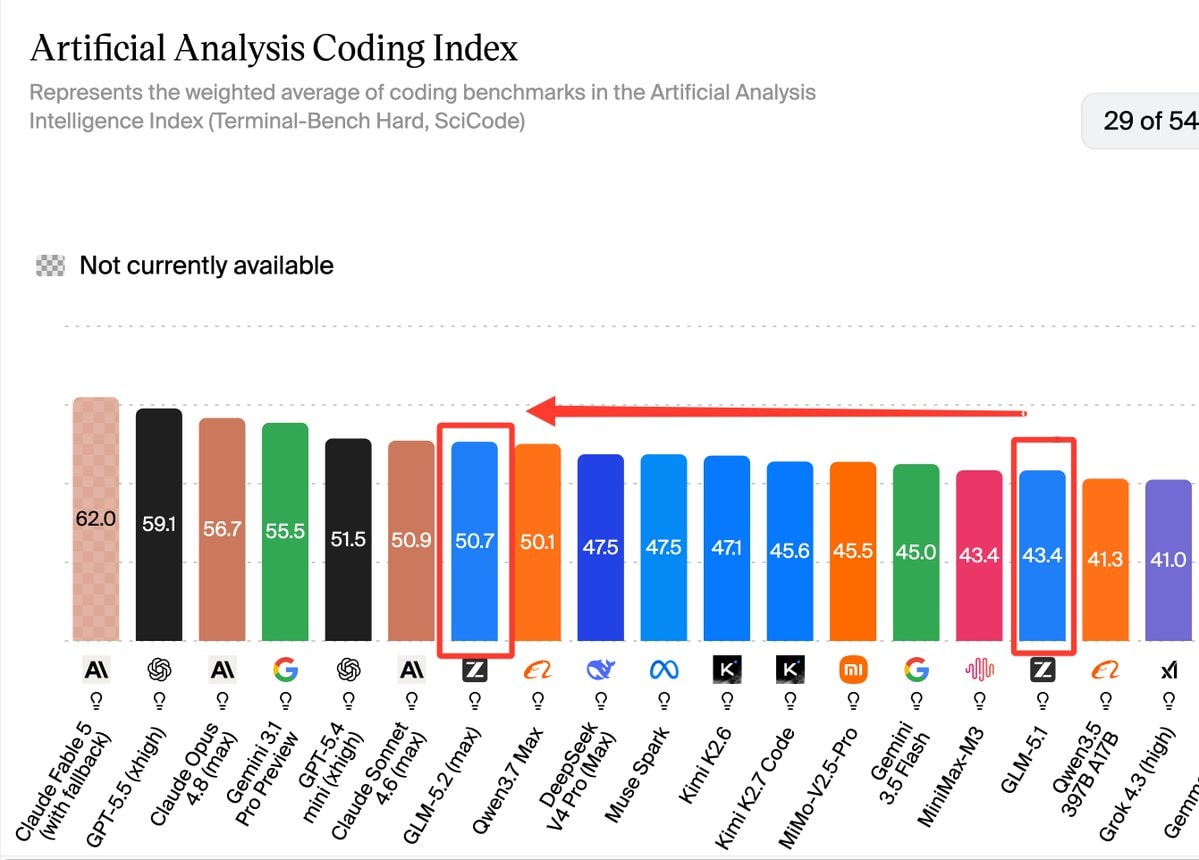
GLM 5.2 Artificial Analysis Coding Index
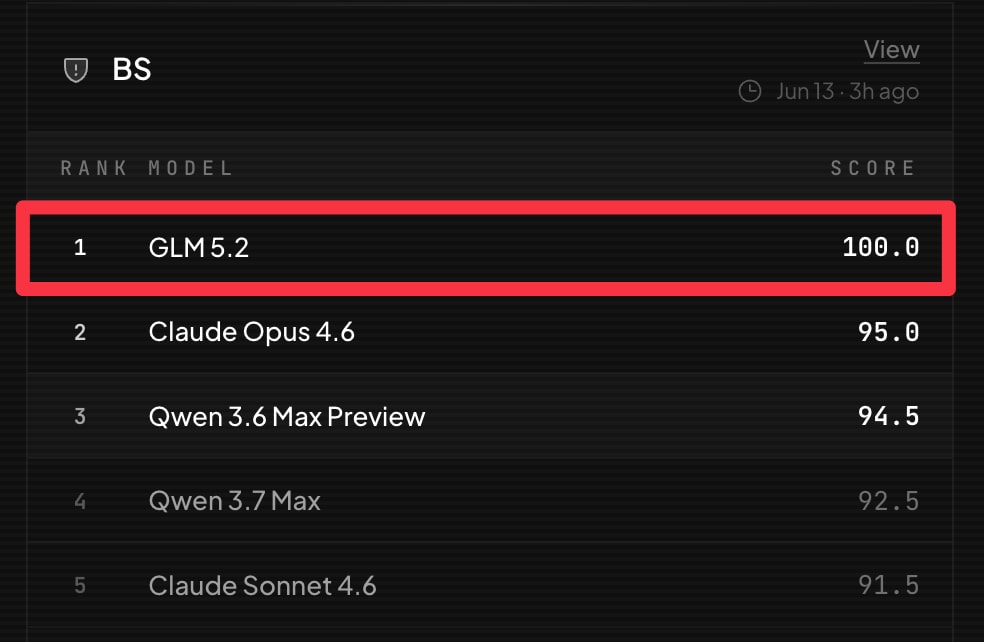
GLM 5.2 perfect score BridgeBench BS