iFANN
    Search iFANN...
    Log in
    Home
    News
    Videos
    Books
    Photos
    GIFs
    Explore
    Polls
    Awards
    iFAMOUS
    Wiki
    Anime
    Rooms
    Notifications
    Messages
    Bookmarks
    Profile
    WikiAwardsiFAMOUSRankingsIndustriesCreator RewardsUser RewardsTermsPrivacyCommunity GuidelinesTakedown / DMCAHelpDevelopers

    © 2026 iFANN

    Home
    Search
    Messages
    Alerts
    Profile
    Photo
    Nate
    Nate@nate_5122mo
    ⭐Andrej Karpathy🏢Google📱Qwen
    Google WikiSkill paper SKILL.md agents

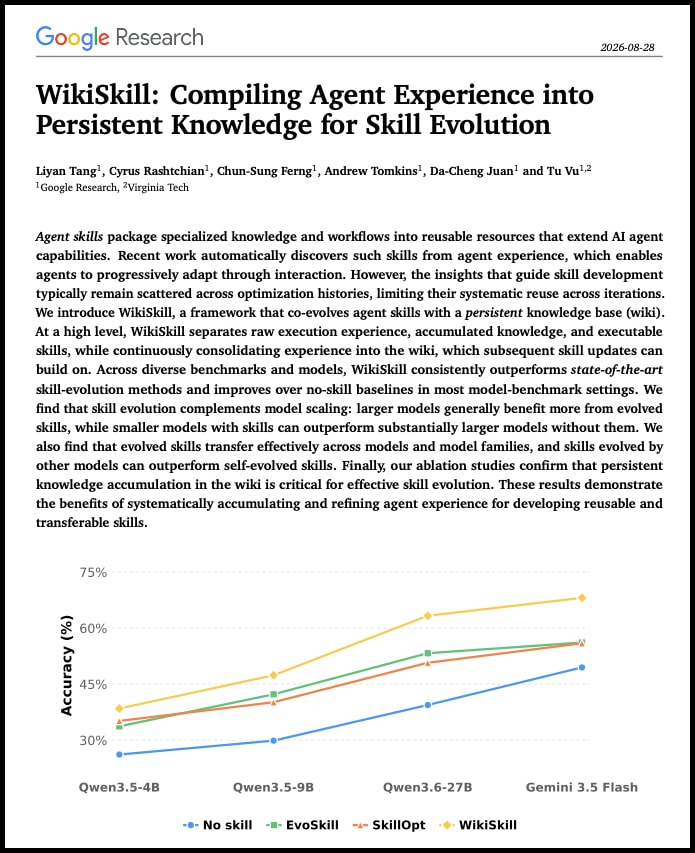
    @nate_512The graph in that Google paper is what got me. Qwen-9B with evolved skills posts 47.4% across five benchmarks. Qwen-27B running bare posts 39.4%. Both Qwen, neither one fine-tuned. Smaller model wins. What skill evolution actually does: the agent takes a swing at a task, reads back its own traces, rewrites its own skill set, and keeps the rewrite only when validation says it helped. EvoSkill, SkillOpt, Trace2Skill all trip on the same thing, the lessons worth keeping end up buried in optimizer history instead of anywhere reusable. WikiSkill's fix is a wiki that lives between the traces and the skills. Karpathy's LLM Wiki is the inspiration. After every run a maintainer sorts the wins and the misses into that wiki, a proposer reads it and edits SKILL.md, and anything that turns out bad rolls back on its own. Numbers back it. WikiSkill clears the best prior method by 3.3 to 12.0 points on all five models tested. The bigger the model the more it gains: 12.3 points on Qwen 4B, 17.5 on 9B, 23.9 on 27B. Skills also travel. Qwen-27B wrote them, Qwen-9B picked them up, SpreadsheetBench went 24.3% to 50.5%. And the wiki is not decorative. Take it out and Gemini 3.5 Flash falls from 63.7% to 48.7%. Most skills out there are still written by hand. A bigger model is not the only way up. Test what evolved skills squeeze out of the one you already own first

    View original post
    Google WikiSkill paper SKILL.md agents

    Photo by @nate_512· Sep 20, 2026· Andrej Karpathy

    About this photo

    The image is a screenshot of a research paper. The focus is on the title "WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution" and a line graph showing accuracy percentages across different models. The mood is academic and informative. Visually notable elements include the Google Research logo and the graph itself, which displays four distinct lines representing different skill evolution methods. ON-SCREEN TEXT: Google Research 2026-08-28 WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution Liyan Tang¹, Cyrus Rashtchian¹, Chun-Sung Ferng¹, Andrew Tomkins¹, Da-Cheng Juan¹ and Tu Vu¹,² ¹Google Research, ²Virginia Tech Accuracy (%) 75% 60% 45% 30% Qwen3.5-4B Qwen3.5-9B Qwen3.6-27B Gemini 3.5 Flash -•- No skill -EvoSkill -SkillOpt -WikiSkill

    See all Andrej Karpathy photosRead the Andrej Karpathy wiki

    ?

    More Andrej Karpathy photos

    See all Andrej Karpathy photos
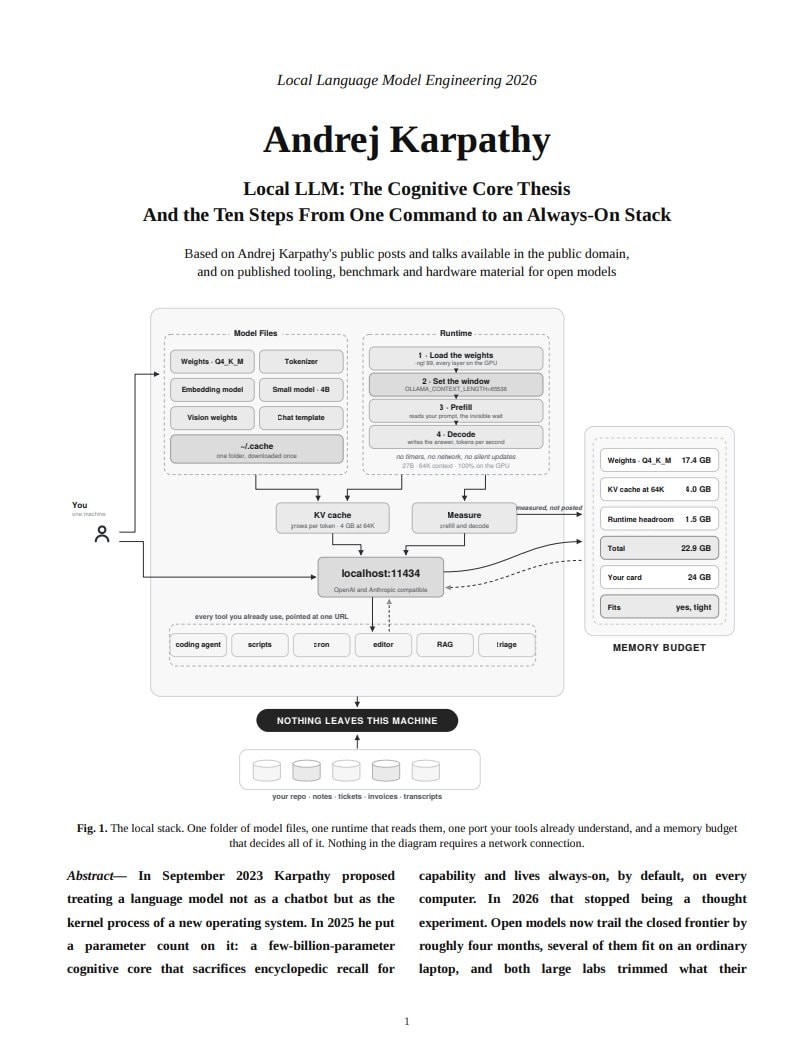
    HackerTube by @KarpathyHackerTube by @KarpathyAndrej Karpathy Local Language Model Engineering 2026Andrej Karpathy Local Language Model Engineering 2026Andrej Karpathy ChatGPT graph engineeringAndrej Karpathy ChatGPT graph engineeringGraphify open source toolGraphify open source toolKarpathy Stanford AI engineering lectureKarpathy Stanford AI engineering lectureClaude Code + Obsidian Second Brain setupClaude Code + Obsidian Second Brain setupAndrej Karpathy interviewAndrej Karpathy interview
    Photo
    Nate
    Nate@nate_5122mo
    ⭐Andrej Karpathy🏢Google📱Qwen
    Google WikiSkill paper SKILL.md agents

    @nate_512The graph in that Google paper is what got me. Qwen-9B with evolved skills posts 47.4% across five benchmarks. Qwen-27B running bare posts 39.4%. Both Qwen, neither one fine-tuned. Smaller model wins. What skill evolution actually does: the agent takes a swing at a task, reads back its own traces, rewrites its own skill set, and keeps the rewrite only when validation says it helped. EvoSkill, SkillOpt, Trace2Skill all trip on the same thing, the lessons worth keeping end up buried in optimizer history instead of anywhere reusable. WikiSkill's fix is a wiki that lives between the traces and the skills. Karpathy's LLM Wiki is the inspiration. After every run a maintainer sorts the wins and the misses into that wiki, a proposer reads it and edits SKILL.md, and anything that turns out bad rolls back on its own. Numbers back it. WikiSkill clears the best prior method by 3.3 to 12.0 points on all five models tested. The bigger the model the more it gains: 12.3 points on Qwen 4B, 17.5 on 9B, 23.9 on 27B. Skills also travel. Qwen-27B wrote them, Qwen-9B picked them up, SpreadsheetBench went 24.3% to 50.5%. And the wiki is not decorative. Take it out and Gemini 3.5 Flash falls from 63.7% to 48.7%. Most skills out there are still written by hand. A bigger model is not the only way up. Test what evolved skills squeeze out of the one you already own first

    View original post
    Google WikiSkill paper SKILL.md agents

    Photo by @nate_512· Sep 20, 2026· Andrej Karpathy

    About this photo

    The image is a screenshot of a research paper. The focus is on the title "WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution" and a line graph showing accuracy percentages across different models. The mood is academic and informative. Visually notable elements include the Google Research logo and the graph itself, which displays four distinct lines representing different skill evolution methods. ON-SCREEN TEXT: Google Research 2026-08-28 WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution Liyan Tang¹, Cyrus Rashtchian¹, Chun-Sung Ferng¹, Andrew Tomkins¹, Da-Cheng Juan¹ and Tu Vu¹,² ¹Google Research, ²Virginia Tech Accuracy (%) 75% 60% 45% 30% Qwen3.5-4B Qwen3.5-9B Qwen3.6-27B Gemini 3.5 Flash -•- No skill -EvoSkill -SkillOpt -WikiSkill

    See all Andrej Karpathy photosRead the Andrej Karpathy wiki

    ?

    More Andrej Karpathy photos

    See all Andrej Karpathy photos
    HackerTube by @KarpathyHackerTube by @KarpathyAndrej Karpathy Local Language Model Engineering 2026Andrej Karpathy Local Language Model Engineering 2026Andrej Karpathy ChatGPT graph engineeringAndrej Karpathy ChatGPT graph engineeringGraphify open source toolGraphify open source toolKarpathy Stanford AI engineering lectureKarpathy Stanford AI engineering lectureClaude Code + Obsidian Second Brain setupClaude Code + Obsidian Second Brain setupAndrej Karpathy interviewAndrej Karpathy interview