LLMFIT open-source local LLM hardware scanner
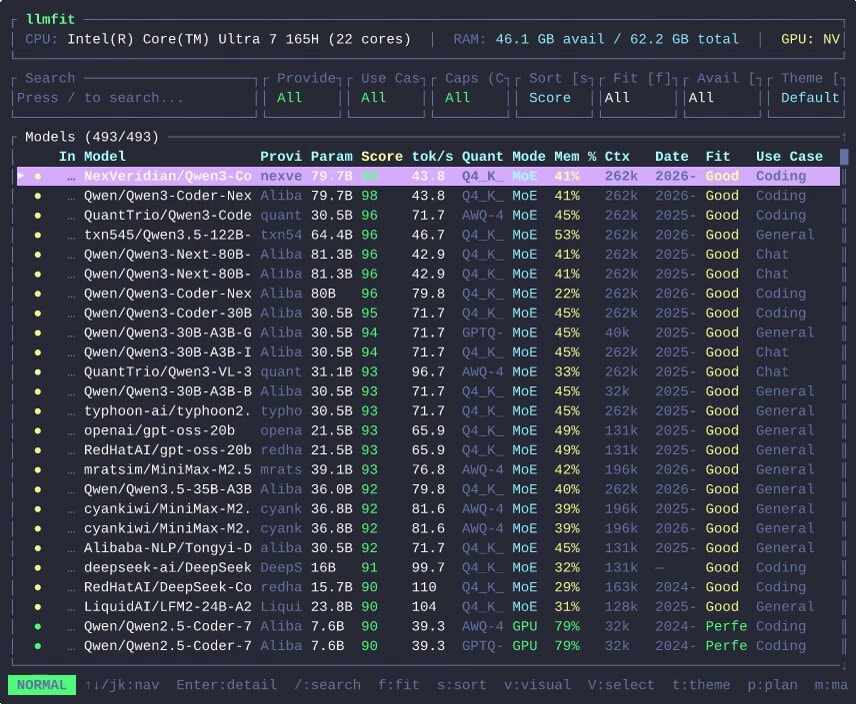
LLMFIT wants you to stop grabbing models that your setup was never going to handle. It's a fresh open-source tool, and the whole move is scanning your machine first so model selection isn't a guessing game anymore. What gets checked: RAM, CPU, GPU(s), and VRAM or unified memory. From there every model lands a score on four fronts. Quality, which leans on parameter count and quantization. Speed, where it estimates tokens per second for the exact backend you're running. Fit, matching memory use against what you've got. And context window support for whatever you're actually trying to do. Then it hands out a label: Perfect, Good, Marginal, or Too Tight. Quantization gets handled for you too. Rather than making you eyeball GGUF sizes by hand, it steps down until the thing fits. Coverage goes wide. Hundreds of models, with Meta, Mistral, Qwen, and DeepSeek among the providers. Ollama, llama.cpp, MLX, and LM Studio all work out of the box. And there's more on top of that. A lightweight TUI, a web dashboard, plus REST API endpoints for anyone wiring it into orchestrators or deployment pipelines. Free, open-source, and it runs on macOS, Linux, and Windows. Honestly feels like step zero before any local download.