iFANN
    Search iFANN...
    Log in
    Home
    News
    Videos
    Photos
    GIFs
    Explore
    Polls
    Awards
    iFAMOUS
    Wiki
    Anime
    Rooms
    Notifications
    Messages
    Bookmarks
    Profile
    WikiAwardsiFAMOUSRankingsIndustriesCreator RewardsUser RewardsTermsPrivacyCommunity GuidelinesTakedown / DMCAHelpDevelopers

    © 2026 iFANN

    Home
    Search
    Messages
    Alerts
    Profile
    Photo
    Nate
    Nate@nate_5121w
    🏢OpenRouter🏢DeepSeek🏢OpenAI
    Inworld Inference Gemma 4 26B latency

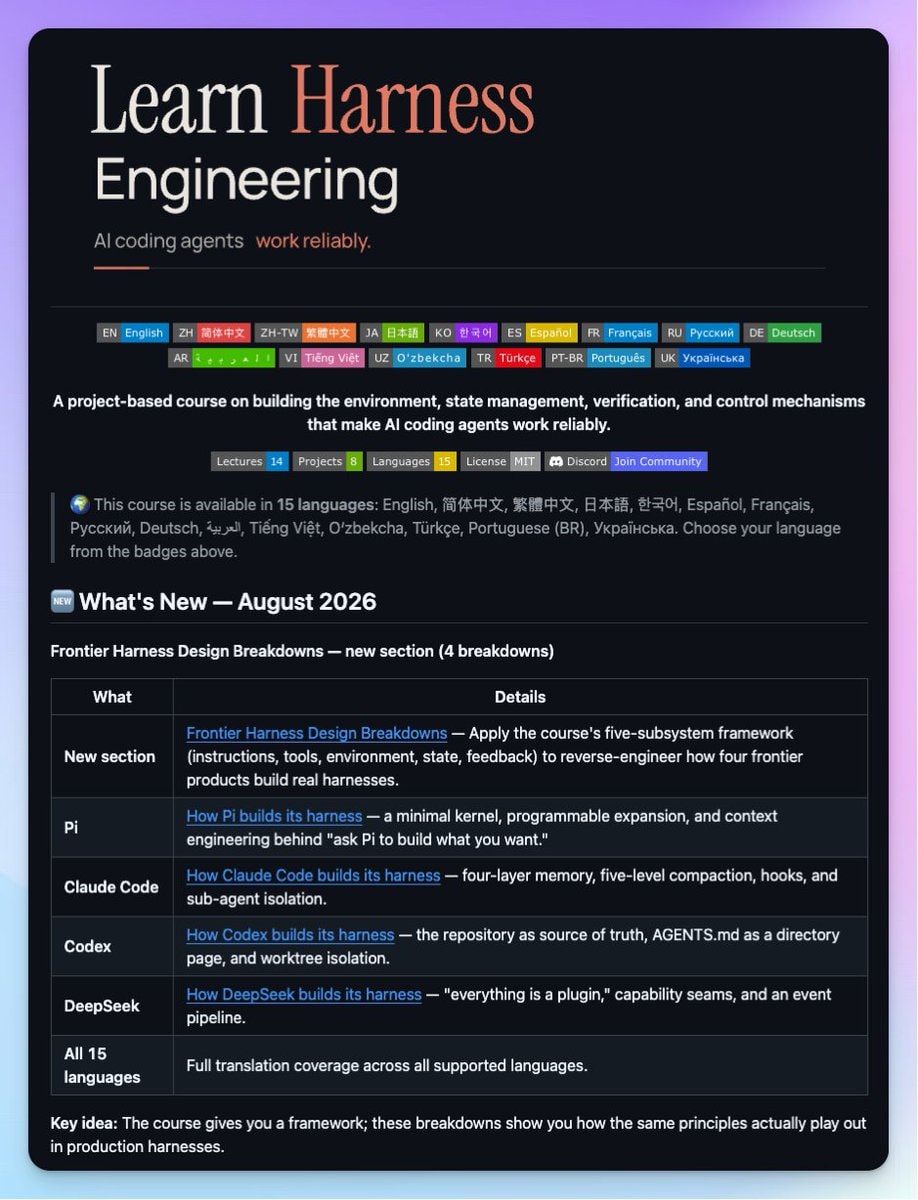
    @nate_512The 95th percentile is where this gets wild. Inworld's Gemma 4 26B hosting starts streaming in 0.31 seconds while the OpenRouter provider median sits at 2.42. That's 7.8x, and it's the kind of tail latency that decides whether an AI tutor or a game character feels alive or feels broken. A two second freeze kills the illusion, so pulling it down to a third of a second is a real shift. Median tells the same story from the other end: 0.17 seconds on Inworld against 0.61 for OpenRouter, which lands at 3.6x faster. Both numbers measure the wait until tokens actually start coming back, not total generation. Inworld Inference is the LLM inference API behind all this, built for devs shipping real-time consumer AI apps. Gemma isn't riding solo either. GLM, DeepSeek, and MiMo are hosted alongside it, and the whole lineup is reachable through an OpenAI compatible API. Istg the latency race is cooked in the best way

    View original post
    Inworld Inference Gemma 4 26B latency

    Photo by @nate_512· Oct 15, 2026· OpenRouter

    About this photo

    The image is a dark-themed infographic presenting data about Inworld Inference. It highlights key metrics like cost savings, reliability, and speed with accompanying charts and statistics. The mood is professional and data-driven, showcasing the company's performance. Notable elements include the "25x since March" growth chart and a bar graph comparing Inworld's performance against other providers. ON-SCREEN TEXT: Inworld, Inworld Inference, The first inference service built for consumer AI., Voice notes in a free app, A call that stays up, A reply before the next step, LOWEST COST, ~40% lower cost, MOST RELIABLE, 99.999%, FASTEST REPLIES, ~8x faster, Than the median provider of the same open model., Reliability across more than 20 million requests a month., Time to first token, against other providers of the same model., 25x since March, Serving tens of trillions of tokens a month, Across every model we host., Inworld, Gemma 4 26B ·

    See all OpenRouter photosRead the OpenRouter wiki

    ?

    No comments yet. Be the first!

    More OpenRouter photos

    See all OpenRouter photos
    Learn Harness Engineering GitHub CourseLearn Harness Engineering GitHub CourseDeepSeek V4.1 Flash NVFP4 locallyDeepSeek V4.1 Flash NVFP4 locallyAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxMac Studio M5 Ultra releaseMac Studio M5 Ultra releaseDeepSeek Harness 10k stars recordDeepSeek Harness 10k stars recordDeepSeek API price increase noticeDeepSeek API price increase noticeFree Claude Code proxyFree Claude Code proxyWhen These Companies Were FoundedWhen These Companies Were FoundedDeepSeek v4 Flash 284B beats GPT 5.6 LunaDeepSeek v4 Flash 284B beats GPT 5.6 LunaOpenRouter US model share collapse 2025-2026OpenRouter US model share collapse 2025-2026GLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexSide by Side Cost Comparison of DeepSeek V4 and Claude CodeSide by Side Cost Comparison of DeepSeek V4 and Claude Code
    Photo
    Nate
    Nate@nate_5121w
    🏢OpenRouter🏢DeepSeek🏢OpenAI
    Inworld Inference Gemma 4 26B latency

    @nate_512The 95th percentile is where this gets wild. Inworld's Gemma 4 26B hosting starts streaming in 0.31 seconds while the OpenRouter provider median sits at 2.42. That's 7.8x, and it's the kind of tail latency that decides whether an AI tutor or a game character feels alive or feels broken. A two second freeze kills the illusion, so pulling it down to a third of a second is a real shift. Median tells the same story from the other end: 0.17 seconds on Inworld against 0.61 for OpenRouter, which lands at 3.6x faster. Both numbers measure the wait until tokens actually start coming back, not total generation. Inworld Inference is the LLM inference API behind all this, built for devs shipping real-time consumer AI apps. Gemma isn't riding solo either. GLM, DeepSeek, and MiMo are hosted alongside it, and the whole lineup is reachable through an OpenAI compatible API. Istg the latency race is cooked in the best way

    View original post
    Inworld Inference Gemma 4 26B latency

    Photo by @nate_512· Oct 15, 2026· OpenRouter

    About this photo

    The image is a dark-themed infographic presenting data about Inworld Inference. It highlights key metrics like cost savings, reliability, and speed with accompanying charts and statistics. The mood is professional and data-driven, showcasing the company's performance. Notable elements include the "25x since March" growth chart and a bar graph comparing Inworld's performance against other providers. ON-SCREEN TEXT: Inworld, Inworld Inference, The first inference service built for consumer AI., Voice notes in a free app, A call that stays up, A reply before the next step, LOWEST COST, ~40% lower cost, MOST RELIABLE, 99.999%, FASTEST REPLIES, ~8x faster, Than the median provider of the same open model., Reliability across more than 20 million requests a month., Time to first token, against other providers of the same model., 25x since March, Serving tens of trillions of tokens a month, Across every model we host., Inworld, Gemma 4 26B ·

    See all OpenRouter photosRead the OpenRouter wiki

    ?

    No comments yet. Be the first!

    More OpenRouter photos

    See all OpenRouter photos
    Learn Harness Engineering GitHub CourseLearn Harness Engineering GitHub CourseDeepSeek V4.1 Flash NVFP4 locallyDeepSeek V4.1 Flash NVFP4 locallyAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxMac Studio M5 Ultra releaseMac Studio M5 Ultra releaseDeepSeek Harness 10k stars recordDeepSeek Harness 10k stars recordDeepSeek API price increase noticeDeepSeek API price increase noticeFree Claude Code proxyFree Claude Code proxyWhen These Companies Were FoundedWhen These Companies Were FoundedDeepSeek v4 Flash 284B beats GPT 5.6 LunaDeepSeek v4 Flash 284B beats GPT 5.6 LunaOpenRouter US model share collapse 2025-2026OpenRouter US model share collapse 2025-2026GLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexSide by Side Cost Comparison of DeepSeek V4 and Claude CodeSide by Side Cost Comparison of DeepSeek V4 and Claude Code