iFANN
    Search iFANN...
    Log in
    Home
    News
    Videos
    Photos
    GIFs
    Explore
    Polls
    Awards
    iFAMOUS
    Wiki
    Anime
    Rooms
    Notifications
    Messages
    Bookmarks
    Profile
    WikiAwardsiFAMOUSRankingsIndustriesCreator RewardsUser RewardsTermsPrivacyCommunity GuidelinesTakedown / DMCAHelpDevelopers

    © 2026 iFANN

    Home
    Search
    Messages
    Alerts
    Profile
    Photo
    Nate
    Nate@nate_51244m
    🏢OpenRouter🏢DeepSeek🏢OpenAI
    Inworld Inference Gemma 4 26B latency

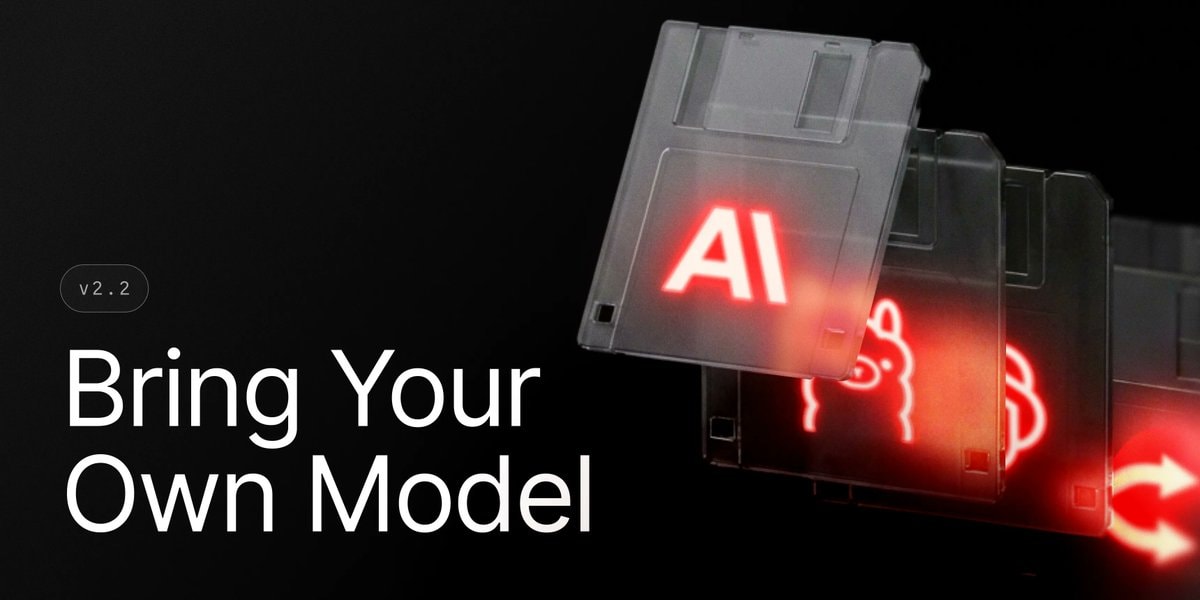
    @nate_512The 95th percentile is where this gets wild. Inworld's Gemma 4 26B hosting starts streaming in 0.31 seconds while the OpenRouter provider median sits at 2.42. That's 7.8x, and it's the kind of tail latency that decides whether an AI tutor or a game character feels alive or feels broken. A two second freeze kills the illusion, so pulling it down to a third of a second is a real shift. Median tells the same story from the other end: 0.17 seconds on Inworld against 0.61 for OpenRouter, which lands at 3.6x faster. Both numbers measure the wait until tokens actually start coming back, not total generation. Inworld Inference is the LLM inference API behind all this, built for devs shipping real-time consumer AI apps. Gemma isn't riding solo either. GLM, DeepSeek, and MiMo are hosted alongside it, and the whole lineup is reachable through an OpenAI compatible API. Istg the latency race is cooked in the best way

    View original post
    Inworld Inference Gemma 4 26B latency

    Photo by @nate_512· Oct 15, 2026· OpenRouter

    About this photo

    The image is a dark-themed infographic presenting data about Inworld Inference. It highlights key metrics like cost savings, reliability, and speed with accompanying charts and statistics. The mood is professional and data-driven, showcasing the company's performance. Notable elements include the "25x since March" growth chart and a bar graph comparing Inworld's performance against other providers. ON-SCREEN TEXT: Inworld, Inworld Inference, The first inference service built for consumer AI., Voice notes in a free app, A call that stays up, A reply before the next step, LOWEST COST, ~40% lower cost, MOST RELIABLE, 99.999%, FASTEST REPLIES, ~8x faster, Than the median provider of the same open model., Reliability across more than 20 million requests a month., Time to first token, against other providers of the same model., 25x since March, Serving tens of trillions of tokens a month, Across every model we host., Inworld, Gemma 4 26B ·

    See all OpenRouter photosRead the OpenRouter wiki

    ?

    No comments yet. Be the first!

    More OpenRouter photos

    See all OpenRouter photos
    Raycast AI Bring Your Own ModelRaycast AI Bring Your Own ModelOpenRouter token volume growth chartOpenRouter token volume growth chartGemini 3.7 Flash OpenRouter pricingGemini 3.7 Flash OpenRouter pricingcity-based team fan reactioncity-based team fan reactionReal Madrid Roma comeback MourinhoReal Madrid Roma comeback MourinhoSame energy, no switch up2Same energy, no switch upZakynthos Island GreeceZakynthos Island GreeceKim Guilfoyle Athens ambassador controversyKim Guilfoyle Athens ambassador controversyNew home keysNew home keysMadison Beer new selfiesMadison Beer new selfiesKash Patel James Bond postKash Patel James Bond postDaejon Love fake 49ers player documentaryDaejon Love fake 49ers player documentaryProBox TV fight card October 16ProBox TV fight card October 16Tems 2027 Grammys submissions2Tems 2027 Grammys submissionsOne Piece charactersOne Piece charactersMan City and Real Madrid both loseMan City and Real Madrid both loseUS stock market lossUS stock market lossEndrick Real Madrid performanceEndrick Real Madrid performance
    Photo
    Nate
    Nate@nate_51244m
    🏢OpenRouter🏢DeepSeek🏢OpenAI
    Inworld Inference Gemma 4 26B latency

    @nate_512The 95th percentile is where this gets wild. Inworld's Gemma 4 26B hosting starts streaming in 0.31 seconds while the OpenRouter provider median sits at 2.42. That's 7.8x, and it's the kind of tail latency that decides whether an AI tutor or a game character feels alive or feels broken. A two second freeze kills the illusion, so pulling it down to a third of a second is a real shift. Median tells the same story from the other end: 0.17 seconds on Inworld against 0.61 for OpenRouter, which lands at 3.6x faster. Both numbers measure the wait until tokens actually start coming back, not total generation. Inworld Inference is the LLM inference API behind all this, built for devs shipping real-time consumer AI apps. Gemma isn't riding solo either. GLM, DeepSeek, and MiMo are hosted alongside it, and the whole lineup is reachable through an OpenAI compatible API. Istg the latency race is cooked in the best way

    View original post
    Inworld Inference Gemma 4 26B latency

    Photo by @nate_512· Oct 15, 2026· OpenRouter

    About this photo

    The image is a dark-themed infographic presenting data about Inworld Inference. It highlights key metrics like cost savings, reliability, and speed with accompanying charts and statistics. The mood is professional and data-driven, showcasing the company's performance. Notable elements include the "25x since March" growth chart and a bar graph comparing Inworld's performance against other providers. ON-SCREEN TEXT: Inworld, Inworld Inference, The first inference service built for consumer AI., Voice notes in a free app, A call that stays up, A reply before the next step, LOWEST COST, ~40% lower cost, MOST RELIABLE, 99.999%, FASTEST REPLIES, ~8x faster, Than the median provider of the same open model., Reliability across more than 20 million requests a month., Time to first token, against other providers of the same model., 25x since March, Serving tens of trillions of tokens a month, Across every model we host., Inworld, Gemma 4 26B ·

    See all OpenRouter photosRead the OpenRouter wiki

    ?

    No comments yet. Be the first!

    More OpenRouter photos

    See all OpenRouter photos
    Raycast AI Bring Your Own ModelRaycast AI Bring Your Own ModelOpenRouter token volume growth chartOpenRouter token volume growth chartGemini 3.7 Flash OpenRouter pricingGemini 3.7 Flash OpenRouter pricingcity-based team fan reactioncity-based team fan reactionReal Madrid Roma comeback MourinhoReal Madrid Roma comeback MourinhoSame energy, no switch up2Same energy, no switch upZakynthos Island GreeceZakynthos Island GreeceKim Guilfoyle Athens ambassador controversyKim Guilfoyle Athens ambassador controversyNew home keysNew home keysMadison Beer new selfiesMadison Beer new selfiesKash Patel James Bond postKash Patel James Bond postDaejon Love fake 49ers player documentaryDaejon Love fake 49ers player documentaryProBox TV fight card October 16ProBox TV fight card October 16Tems 2027 Grammys submissions2Tems 2027 Grammys submissionsOne Piece charactersOne Piece charactersMan City and Real Madrid both loseMan City and Real Madrid both loseUS stock market lossUS stock market lossEndrick Real Madrid performanceEndrick Real Madrid performance